class: center, middle, inverse, title-slide .title[ # Hierarchical Modeling in <br>Fisheries Integrated Modeling System (FIMS) ] .subtitle[ ## DFO Training<br>Nanaimo ] .author[ ### Andrea Havron, NOAA Fisheries OST<br><a href="mailto:andrea.havron@noaa.gov" class="email">andrea.havron@noaa.gov</a><br> ] .date[ ### 2026/10/07 ] --- layout: true .footnote[U.S. Department of Commerce | National Oceanic and Atmospheric Administration | National Marine Fisheries Service] <style type="text/css"> code.cpp{ font-size: 20px; } code.r{ font-size: 20px; } code.Rcpp{ font-size: 20px; } </style> <!-- Start of slides --> --- # Outline - Hierarchical Modeling in Stock Assessments - C++ architecture - User Interface - Future Development Plans --- # Hierarchical Modeling in Stock Assessments <br> <br> .center[ .large[ `\(Index \sim LogNormal(\hat{\mathbf{I}}, \sigma_{I})\)` <br> `\(\hat{\mathbf{I}} = f(Growth, Maturity, Mortality, \mathbf{Recruitment}, Selectivity)\)` <br> `\(\log(\mathbf{Recruitment}) \sim Normal(\log(\hat{R}), \sigma_{R})\)` ]] --- # Fitting Hierarchical Models: Speed vs. Accuracy .pull-left[ **Penalized likelihood** - Fixed effects estimation (fastest) - Uses a Constrained optimization approach **Laplace approximation** - Random effects estimation (moderate) - Uses 2nd-order Taylor series approximation **MCMC** - Full posterior sampling (slowest) - Asymptotically exact posterior ] .pull-right[ 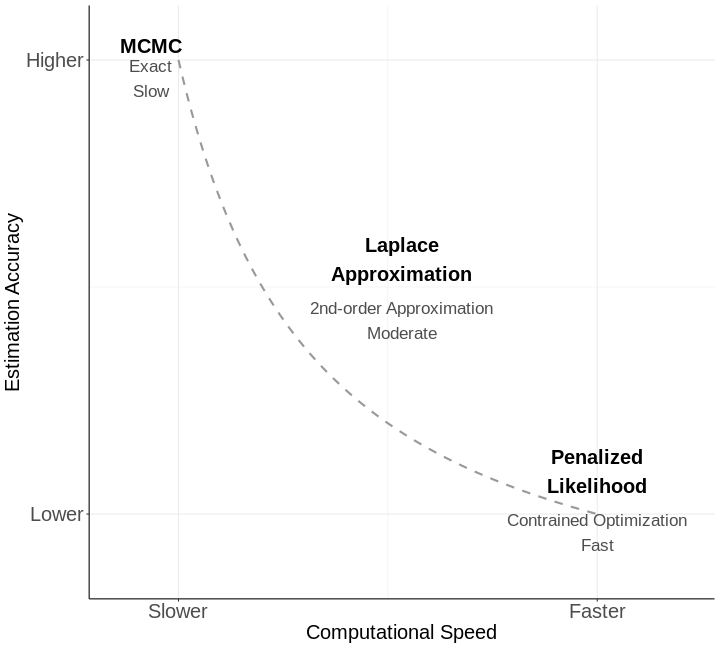<!-- --> ] --- # Guiding Principles in Design <br><br> - Generic and Flexible - Extensible - Separate the biological math from the statistics - Dependency on TMB and access to the Laplace Approximation --- .large[**Decoupling Biological Processes from Statistical Likelihood**] <div id="htmlwidget-0c948ce9f3218bc14cf4" style="width:100%;height:85%;" class="grViz html-widget"></div> <script type="application/json" data-for="htmlwidget-0c948ce9f3218bc14cf4">{"x":{"diagram":"\ndigraph fims {\n # Global settings\n graph [rankdir=LR, bgcolor=\"transparent\", compound=true, nodesep=0.5, ranksep=0.6]\n node [shape=box, style=\"filled, rounded\", color=\"#5b8db8\", fillcolor=\"#f0f7ff\", fontname=\"Arial\", fontcolor=\"#333333\", fontsize=28, width=2.5, height=0.8]\n edge [color=\"#666666\", arrowhead=vee, penwidth=1.2, fontsize = 24]\n\n # User Layer\n subgraph cluster_user {\n label=\"User Layer\"; fontname=\"Arial-Bold\"; fontcolor=\"#5b8db8\"; style=\"dashed\"; color=\"#5b8db8\"; fontsize = 28;\n node [fillcolor=\"#e1f5fe\", color=\"#01579b\"]\n A [label=\"R User Interface\"]\n }\n\n # Central Dispatch\n subgraph cluster_logic {\n label=\"Central Dispatch\"; fontname=\"Arial-Bold\"; fontcolor=\"#c88a2a\"; style=\"dashed\"; color=\"#c88a2a\"; fontsize = 28;\n node [fillcolor=\"#fff3e0\", color=\"#e65100\"]\n B [label=\"Rcpp Interface\"]\n C [label=\"FIMS.cpp\"]\n D [label=\"Information\"]\n }\n\n # Calculation Engine\n subgraph cluster_engine {\n label=\"Calculation Engine\"; fontname=\"Arial-Bold\"; fontcolor=\"#4f9a63\"; style=\"dashed\"; color=\"#4f9a63\"; fontsize = 28;\n node [fillcolor=\"#e8f5e9\", color=\"#2e7d32\"]\n \n E [label=\"Population Dynamics\"]\n H [label=\"Catch-At-Age\"]\n F [label=\"Distributions\"]\n J [label=\"Data\"]\n }\n\n # Results\n subgraph cluster_results {\n label=\"Results\"; fontname=\"Arial-Bold\"; fontcolor=\"#b85a7a\"; style=\"dashed\"; color=\"#b85a7a\"; fontsize = 28;\n node [fillcolor=\"#fce4ec\", color=\"#880e4f\", fontsize = 24]\n G [label=\"model.hpp\"]\n I [label=\"Negative Log-Likelihood\"]\n }\n\n # Layout constraints (forcing order)\n {rank=same; B C}\n {rank=same; E H F J}\n\n # Edges\n A -> B\n A -> C\n B -> D\n D -> E\n D -> H\n\n D -> F\n D -> J \n \n J -> F [constraint=false, style=solid]\n E -> H\n \n # Grouping the outputs to model.hpp\n {H F} -> G\n C -> G\n G -> I\n \n # Feedback loops (using \"constraint=false\" so they don\"t mess up the LR flow)\n I -> C [constraint=false, style=dotted, label=\"value/gradient\", fontsize = 28]\n}\n","config":{"engine":"dot","options":null}},"evals":[],"jsHooks":[]}</script> --- # Globally Available Variable Map variable\_map(Parameter ID, Pointer to the Parameter in Memory) .pull-left[ <br> <div id="htmlwidget-26818cfd297ade1d17f2" style="width:100%;height:50%;" class="grViz html-widget"></div> <script type="application/json" data-for="htmlwidget-26818cfd297ade1d17f2">{"x":{"diagram":"\ndigraph fims {\n # Global settings\n\n graph [rankdir=LR, bgcolor=\"transparent\", compound=true, nodesep=0.5, ranksep=0.6]\n node [shape=box, style=\"filled, rounded\", color=\"#5b8db8\", fillcolor=\"#f0f7ff\", fontname=\"Arial\", fontcolor=\"#333333\", fontsize=28 width=2.5, height=0.8]\n edge [color=\"#666666\", arrowhead=vee, penwidth=1.2, fontsize = 28]\n\n\n # Central Dispatch\n subgraph cluster_logic {\n label=\"Central Dispatch\"; fontname=\"Arial-Bold\"; fontcolor=\"#ffffff\"; style=\"dashed\"; color=\"#ffffff\"; fontsize = 28;\n node [fillcolor=\"#fff3e0\", color=\"#e65100\"]\n A [label=\"Rcpp Interface\"]\n B [label=\"Variable Map\"]\n }\n\n # Calculation Engine\n subgraph cluster_engine {\n label=\"Calculation Engine\"; fontname=\"Arial-Bold\"; fontcolor=\"#4f9a63\"; style=\"dashed\"; color=\"#4f9a63\"; fontsize = 28;\n node [fillcolor=\"#e8f5e9\", color=\"#2e7d32\"]\n \n D [label=\"Population Dynamics\"]\n E [label=\"Catch-At-Age\"]\n F [label=\"Distributions\"]\n G [label=\"Data\"]\n }\n\n\n # Layout constraints (forcing order)\n {rank=same; D E F G}\n\n # Edges\n {A,D} -> B\n\n D -> E\n E -> F\n G -> F [constraint=false, style=solid]\n\n B -> F\n\n \n}\n","config":{"engine":"dot","options":null}},"evals":[],"jsHooks":[]}</script> ] .pull-right[ **Rcpp Interface** <br> _BevertonHolt Interface_<br> ```cpp info //link to information.hpp r // link to recruitment backend // interface parameter that gets // user value from R Variable log_rzero // ID assigned by interface int ID = log_rzero.id() // Store back-end log_rzero in the // variable map using the interface ID variable_map[ID] = &(r)->log_rzero ``` ] --- # Globally Available Variable Map variable\_map(Parameter ID, Pointer to the Parameter in Memory) .pull-left[ **Rcpp Interface** <br>Populates the variable map with pointers to all model parameters, including random effects.<br><br> **Information** <br>Stores the variable map, which is accessible across all C++ files. <br><br> **Distributions** <br>Accesses the variable map to compute likelihood contributions. ] --- # Globally Available Variable Map variable\_map(Parameter ID, Pointer to the Parameter in Memory) .pull-left[ **Rcpp Interface** <br>Populates the variable map with pointers to all model parameters, including random effects.<br><br> **Information** <br>Stores the variable map, which is accessible across all C++ files. <br><br> **Distributions** <br>Accesses the variable map to compute likelihood contributions. ] .pull-right[ **Prior Likelihood**<br> observed_value -> parameter <br><br> **Random Effects Likelihood**<br> observed_value -> random effect parameter<br> expected_value -> derived quantity (or vector of 0s) <br><br> **Data Likelihood**<br> observed_value -> data vector<br> expected_value -> derived quantity ] --- # Add Prior Likelihood to the Model ``` r library(FIMS) # Prepare the package data for being used in a FIMS model data("data_big") data_4_model <- FIMSFrame(data_big) # Set up the default configurations and parameters for the model default_parameters <- setup_default_parameters(data = data_4_model) # initialize model using the power user interface or setup_default_* functions slope_mean <- 1.5; slope_sd <- 3 slope_prior <- methods::new(DnormDistribution) slope_prior$expected_values$resize(2) slope_prior$expected_values[1]$value <- slope_mean slope_prior$expected_values[2]$value <- slope_mean slope_prior$log_sd[1]$value <- log(slope_sd) slope_prior$set_distribution_links("prior",c(fleet1$slope$get_id(), fleet2$slope$get_id())) ``` --- # One Objective, Two Estimation Modes ``` r # Build objective from FIMS/TMB ingredients FIMS::CreateTMBModel() parameters <- list(p = get_fixed(), re = get_random()) obj <- TMB::MakeADFun( data = list(), parameters, random = "re", DLL = "FIMS", silent = TRUE ) # Frequentist path fit <- stats::nlminb(start = obj$par, objective = obj$fn, gradient = obj$gr) # Bayesian path (same objective) posterior <- SparseNUTS::sample_snuts( obj = obj, iter_warmup = 1000, iter_sampling = 1000, chains = 4 ) ``` --- # Connecting Random Effects to TMB ``` r recruitment$log_devs[i]$set_estimation_type("random_effects") ``` In the Rcpp Interface, if a parameter's estimation type is set to "random_effects": - The parameter gets added to the global `random_effects_parameters` vector. - An R function returns the list of random effects parameters for a model. - The random effects list is passed into FIMS.cpp through MakeADFun and is linked to the global `random_effects_parameters` vector. ``` r parameters <- list( p = get_fixed(), re = get_random() ) obj <- TMB::MakeADFun( data = list(), parameters, DLL = "FIMS", silent = TRUE, map = map, random = "re" ) ``` --- # Default FIMS Model ``` r library(FIMS) # Prepare the package data for being used in a FIMS model data("data_big") data_4_model <- FIMSFrame(data_big) # Set up the default configurations and parameters for the model default_parameters <- setup_default_parameters( data = data_4_model ) # run the model fit <- default_parameters |> initialize_fims(data = data_4_model) |> fit_fims(optimize = TRUE) ``` --- # Recruitment Deviations are random effects by default ``` r default_parameters |> dplyr::filter( label == "log_devs" ) ``` ``` ## # A tibble: 29 × 11 ## module_name fleet module_type label age length timing value estimation_type distribution_type distribution ## <chr> <chr> <chr> <chr> <dbl> <dbl> <int> <dbl> <chr> <chr> <chr> ## 1 Recruitment <NA> BevertonHolt log_devs NA NA 2 0 random_effects process Dnorm ## 2 Recruitment <NA> BevertonHolt log_devs NA NA 3 0 random_effects process Dnorm ## 3 Recruitment <NA> BevertonHolt log_devs NA NA 4 0 random_effects process Dnorm ## 4 Recruitment <NA> BevertonHolt log_devs NA NA 5 0 random_effects process Dnorm ## 5 Recruitment <NA> BevertonHolt log_devs NA NA 6 0 random_effects process Dnorm ## 6 Recruitment <NA> BevertonHolt log_devs NA NA 7 0 random_effects process Dnorm ## 7 Recruitment <NA> BevertonHolt log_devs NA NA 8 0 random_effects process Dnorm ## 8 Recruitment <NA> BevertonHolt log_devs NA NA 9 0 random_effects process Dnorm ## 9 Recruitment <NA> BevertonHolt log_devs NA NA 10 0 random_effects process Dnorm ## 10 Recruitment <NA> BevertonHolt log_devs NA NA 11 0 random_effects process Dnorm ## # ℹ 19 more rows ``` --- # Change to fixed effect Estimate with constrained optimization (penalized likelihood) ``` r # set estimation_type of log_devs to fixed_effects default_parameters <- default_parameters |> dplyr::mutate( estimation_type = ifelse(label == "log_devs", "fixed_effects", estimation_type) ) # fix Recruitment Distribution log_sd to "constant" default_parameters <- default_parameters |> dplyr::mutate( estimation_type = ifelse(label == "log_sd" & module_name == "Recruitment", "constant", estimation_type) ) ``` --- # Sparse parameterization of recruitment $$ `\begin{align} log\_r &\sim Normal(\widehat{log\_r}, \sigma_{r})\\ \widehat{log\_r} &= log(BevertonHolt(SSB, parameters)) \end{align}` $$ ``` r default_parameters <- default_parameters |> dplyr::filter(!(label == "log_devs" & module_name == "Recruitment")) |> dplyr::rows_append( tibble::tibble( module_name = "Recruitment", module_type = "BevertonHolt", label = "log_r", timing = 1:30, value = rep(0,30), estimation_status = "random_effects", distribution_type = "process", distribution = "Dnorm" ) ) ``` --- # Upcoming User Interface Enhancements New helper functions to set random effects for any process (GitHub Issue [#1235](https://github.com/NOAA-FIMS/FIMS/issues/1235)) <br> ``` r add_process( module_name = “selectivity”, fleet_name = “fleet1”, specification_type = “semi_parametric”, strucutre = “AR1”, base_function = “logistic”, logit_rho = 0) add_priors( fleet = c(fleet1, fleet2), module = selectivity, slope ~ normal(1.5, 10), inflection_point ~ normal(2, 10) ) ``` --- # Future FIMS Hierarchical Development Goals <br> .large[ - Flexible priors via **automatic Jacobian** transformations (Draft PR [#1495](https://github.com/NOAA-FIMS/FIMS/pull/1495)) <br><br> - Add a generic **ARn** distribution (Issue [#582](https://github.com/NOAA-FIMS/FIMS/issues/582)) <br><br> - Add multivariate functionality - **GMRF** distribtion (Issue [#582](https://github.com/NOAA-FIMS/FIMS/issues/582)) - Ability to set **multivariate pointers** <br><br> - Fully develop **non-parametric** and **semi-parametric** functionality for all time-varying parameters - Age-based selectivity Closed Issue [#1206](https://github.com/NOAA-FIMS/FIMS/issues/1206) <br><br> - Add OSA residuals (Issue [#546](https://github.com/NOAA-FIMS/FIMS/issues/546)) ] --- # Summary <br> .large[ - FIMS Random Effects and Priors are designed to be **generic**, **flexible**, and **extensible** <br><br> - FIMS keep the biological math **separate** from the statistical likelihood <br><br> - The global **variable map** allows any **parameter** or **derived quantity** to be linked to random effect or prior distributions <br><br> - One TMB object for both **MLE optimization** and **Bayesian MCMC** <br><br> - The current **default model** fits recruitment deviations as **random effects** with a Normal iid distribution ] --- # 👋 Thank you! <div style="text-align: center;"> <img src="static/FIMS_hexlogo.png" style="width: 100%; max-width: 300px;" /> </div> 📩 andrea.havron@noaa.gov